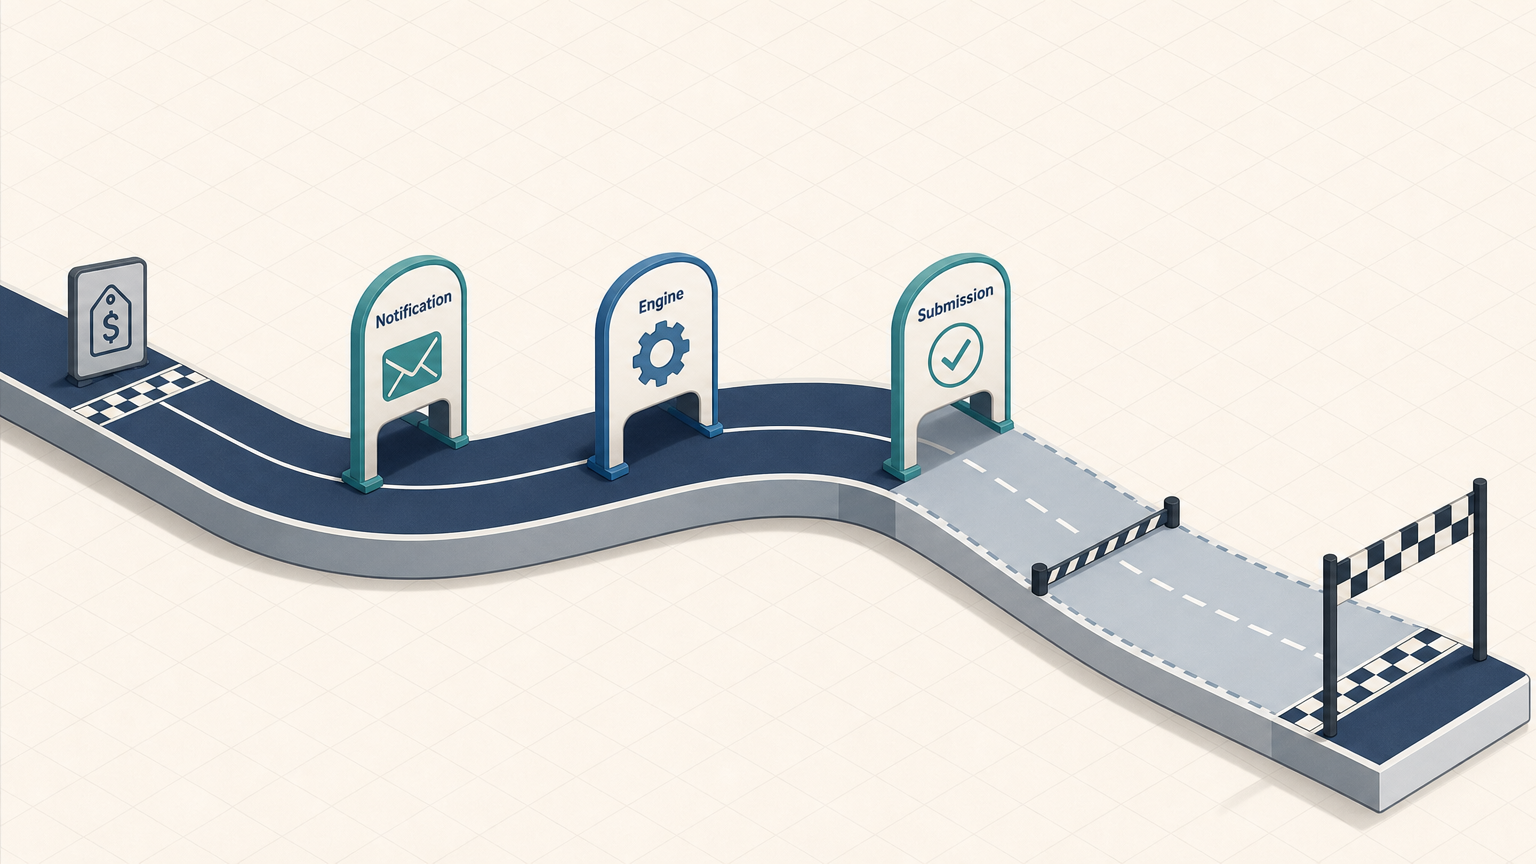
A repricer is fast only if it closes the entire latency chain: from the moment a competitor's offer changes on the marketplace to the moment your new price is accepted and shoppers can see it. Internal calculation time is one segment of that chain, and usually the smallest. Most "instant" and "millisecond" claims time only that segment.
This article defines the segments, explains which ones a repricer controls, and gives you a framework for evaluating speed claims. All figures about Informed Repricer come from its published Overdrive architecture documentation.
Speed is the time between a competitor's change and your accepted price
Operationally, repricing speed determines how long you sit outside the Buy Box after a competitor moves. Every second of lag is a window in which the competitor holds ownership. The metric that matters is end-to-end latency, with a defined start and stop:
- Start: the marketplace's offer-change timestamp for the competitor's price.
- Stop: the marketplace's acceptance of your new price (buyer-visible propagation follows, and internal timers never capture it).
Faster isn't always better. A repricer that reacts to every competitor tick without strategy constraints can drive destructive price cuts. Speed is valuable when paired with rules that know when to lower, hold, or raise a price. For the ownership side of this, see how Buy Box percentage trades against margin.
Event-driven architectures beat polling on time-to-first-reaction
Polling reads competitor data on a schedule. Its failure modes are predictable: a stale-data window equal to the polling interval, wasted API calls when nothing changed, and added pressure on rate limits.
Event-driven repricing consumes notifications (for Amazon, SP-API offer-change notifications) as they arrive. Typical implementation uses a message queue such as SQS, with worker pools pulling messages, deduplicating by (listing, target price, source event timestamp), and passing them to the pricing engine.
The timeline looks like this:
offer change → notification delivery → queue pickup → repricer calculation → submission → marketplace acceptance → buyer-visible
Event-driven design shortens the middle of that chain. It can't remove the ends. Informed Repricer states that delivery, queueing, and processing after a competitor's change "on average add up to a full second excluding any processing of the data by the repricer." That is why millisecond repricing from offer change to acceptance isn't physically achievable.
Two update paths trade single-listing latency for throughput
Marketplace APIs generally offer a bulk path and a direct path. Informed Repricer documents these limits:
| Marketplace | Path | Batch size | Rate | Max price changes/hour |
|---|---|---|---|---|
| Amazon | Batch feed | 25,000 listings | 5 submissions per 5 min (burst 15) | 1,500,000 (60 feeds) |
| Amazon | Patch call | 1 listing | 5 requests/sec (burst 5) | 18,000 |
| Walmart | Batch feed | 10,000 listings | 10 submissions/hour | 100,000 |
| Walmart | Direct update | 1 listing | 100 requests/hour | 100 |
Feeds are asynchronous and move enormous volume, but a listing waits for the next batch. Patch and direct calls are synchronous and quick per listing, but capped in total volume. Walmart's direct limit of 100 changes per hour shows how scarce priority capacity can be.
These limits are drawn from shared, account-level capacity. Every listing competes for the same pool, so one listing's speed depends on global concurrency and throttle handling.
The practical pattern is lane routing: send high-churn, high-value listings through the direct-update lane and everything else through batch feeds. Informed Repricer's Overdrive works this way. It isolates selected listings so other listings don't consume their capacity, while non-Overdrive listings join the next batch feed, typically within 60 to 120 seconds.
Rate limits are the hard ceiling on submission, and retries need discipline
Rate limits constrain submission, not compute. Most are token-bucket style: capacity refills at a steady rate and bursts spend stored tokens. Average throughput can look healthy while worst-case behavior under a burst of competitor moves is far worse.
Sound handling includes:
- Backoff with jitter: exponential backoff with randomized delay on throttling responses, honoring any Retry-After semantics, so retries from many workers don't synchronize.
- Circuit breaking: pause a lane when failure rates spike instead of feeding a cascade.
- Debouncing: when a competitor changes price three times in two seconds, coalesce and submit only the latest effective price. Batching raises throughput but adds staleness, so keep windows short on priority lanes.
- Idempotency: retries and duplicate notifications must resolve to the same outcome. Deduplication keys prevent a replayed event from writing an outdated price.
Compute scales horizontally, marketplace acceptance doesn't
Workers scale out easily. Submission doesn't, because account throttles and marketplace processing bound it. Good worker design therefore uses bounded concurrency per marketplace and account, with separate pools per update path and priority tier.
Autoscaling should key off queue depth, processing latency, and throttle rate. CPU-only scaling reacts too late, and adding workers during throttling just creates more rejected calls.
The flow is: controller → queue → workers → pricing engine → submission gateway → acceptance tracking. Informed Repricer reports an average internal calculation step of about 70 ms in Overdrive. Shaving that further gains little, since marketplace latency dominates.
Fresh data matters more than fast data
Caching competitor snapshots cuts API reads but risks acting on stale prices. A workable pattern uses short TTLs tuned to event cadence and revalidates only when a decision depends on the value. Stale caches combined with aggressive rules can produce oscillation, where two automated sellers chase each other's old prices. Strategy constraints such as floors, ceilings, and hold rules reduce unnecessary changes and keep speed from becoming thrash.
Verifiable speed claims need percentile metrics at defined boundaries
A claim is verifiable only if each metric maps to a pipeline boundary:
- Internal compute time: processing start to decision.
- Time-to-submit: notification received to request issued.
- Time-to-acceptance: request issued to acceptance response (or async feed completion).
- End-to-end: offer-change timestamp to confirmed acceptance.
Trace each boundary and report P50, P95, and P99 separately for compute and end-to-end, per marketplace and per update path. Alert on queue lag, throttle rate, retry counts, and submission failures. A reasonable SLO might page when P95 end-to-end exceeds target for several consecutive minutes.
Informed Repricer reports sub-2-second end-to-end repricing in Overdrive, from Amazon's offer-change timestamp to marketplace acceptance. Note that it also warns Amazon and Walmart can deprioritize updates at peak load or for lower-priority listings, by several minutes commonly and up to 8 hours at worst. Acceptance isn't the same as buyer-visible.
An audit checklist for comparing repricer speed claims
Ask any vendor, including us:
- Where does the timer start: your own receipt of data, or the marketplace's offer-change timestamp?
- Where does it stop: calculation finished, request sent, or acceptance confirmed?
- Is the figure a best case, an average, or a percentile?
- Does it cover all listings or a prioritized subset?
- How are throttling and batch waits counted?
For a fuller method, see this verifiable speed comparison. Speed that survives these questions comes from event-driven ingestion, lane isolation, disciplined rate-limit handling, and honest measurement of the parts no repricer controls.